Continual Learning
I Taught a Neural Network to Remember Things (It Mostly Failed)
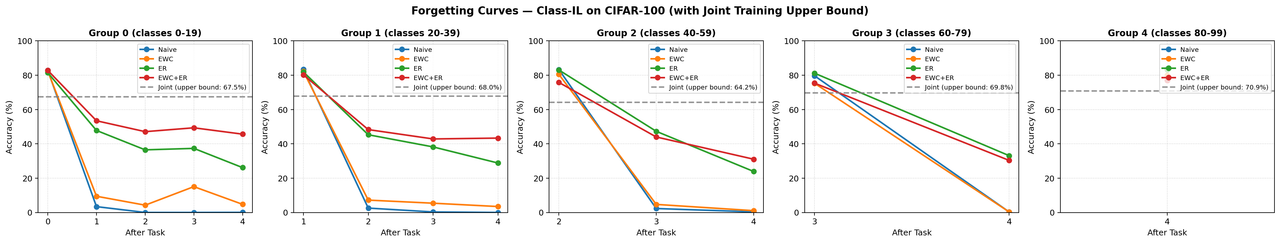
So I ran an experiment to see how badly a neural network forgets things when you teach it new stuff. Spoiler: it's really bad. Like, embarrassingly bad. But then I tried some tricks to fix it and things got interesting.
Let me walk you through what I built, what broke, and what actually worked.
The Problem Nobody Talks About Enough
Here's a scenario. You train a model to detect 20 diseases from medical scans. It works great. Six months later your hospital wants to add 20 more diseases to the model. Easy right? Just train it on the new ones.
Except when you do that, the model completely forgets the original 20 diseases. Not partially forgets. Not gets a little confused. Completely. Wipes. Them. Out.
This is called catastrophic forgetting and it's one of the more annoying unsolved problems in deep learning. The model isn't stupid. It's just that gradient descent doesn't care about what the network used to know. It only cares about minimizing the current loss. So it'll happily destroy everything it learned before if that's what it takes to get good at the new task.
This is the continual learning problem. How do you teach a model new things without it forgetting old things?
The Setup
I took CIFAR-100 which is a dataset of 100 classes of everyday stuff. Apples, buses, dolphins, mushrooms, you name it. 50,000 training images total, 500 per class.
Instead of training on all 100 classes at once, I split them into 5 sequential tasks of 20 classes each:
Task 0: classes 0 to 19   (10,000 images)
Task 1: classes 20 to 39  (10,000 images)
Task 2: classes 40 to 59  (10,000 images)
Task 3: classes 60 to 79  (10,000 images)
Task 4: classes 80 to 99  (10,000 images)
The rule: once you move to Task 1, Task 0's data is gone. The model has to learn each task sequentially with no access to previous data. After all 5 tasks, I test it on all 100 classes at once with no hints about which task an image came from. This is called Class Incremental Learning and it's the hardest standard setting for continual learning.
The model is a ViT-Tiny pretrained on ImageNet. Small, fast, 5.7M parameters. The head has 100 output neurons from day one because in class-IL the model needs to output across all classes at any point.
I compared 4 approaches plus a joint training upper bound:
- Naive sequential training (the "just fine-tune and watch it burn" baseline)
- EWC (Elastic Weight Consolidation)
- Experience Replay
- EWC + ER combined
- Joint training (train on all 100 classes at once, the theoretical ceiling)
Method 1: Naive Sequential Training
No tricks. Just fine-tune on each task in sequence with AdamW at lr=1e-4, 3 epochs per task, then move on.
Here's what happened to Group 0 (the first 20 classes) over time:
After Task 0: 82.80%   (just learned it, great)
After Task 1:  3.40%   (yikes)
After Task 2:  0.00%   (dead)
After Task 3:  0.00%   (still dead)
After Task 4:  0.05%   (somehow worse than random)
After learning all 5 tasks the final breakdown looked like this:
Group 0 (0 to 19):   0.05%
Group 1 (20 to 39):  0.00%
Group 2 (40 to 59):  0.35%
Group 3 (60 to 79):  0.30%
Group 4 (80 to 99):  83.95%
Overall:             16.93%
The model became a specialist in the last thing it learned and completely lost everything else. That 16.93% overall is basically just Group 4 carrying the whole thing. The other 80 classes are effectively dead.
This is catastrophic forgetting in its full glory. The model isn't being dumb. It's doing exactly what it's told. Minimize loss on the current task. The problem is that doing that aggressively destroys the weights that were useful for old tasks.
Method 2: EWC (Elastic Weight Consolidation)
EWC is based on a pretty elegant idea. Not all weights are equally important for a task. Some weights, if you change them, will destroy Task 0's performance. Others can be moved freely without affecting it at all.
So what if after finishing Task 0 you figured out which weights matter most, and then penalized the optimizer for changing them during Task 1 training?
The tool for measuring "how important is this weight" is the Fisher Information Matrix. The intuition is: if you perturb a weight slightly and the loss shoots up, that weight is critical. If the loss barely moves, that weight is expendable. Fisher captures this curvature per parameter.

After Task 0, you compute the Fisher and snapshot the weights. During Task 1 training, the loss becomes:
total loss = task loss + (lambda / 2) * sum over all parameters of (Fisher_i * (param_i - snapshot_i)^2)
For each parameter, the penalty is: how important was this weight times how much has it moved from where it was. The optimizer can still change weights but it pays a price proportional to their importance.
Lambda controls the stiffness. Too small and the penalty is ignored. Too large and the model can't learn anything new.
I used lambda=400 and computed Fisher on 500 samples per task using the empirical Fisher (squared gradients). Here are the results:
Group 0 (0 to 19):   4.75%
Group 1 (20 to 39):  3.45%
Group 2 (40 to 59):  1.05%
Group 3 (60 to 79):  0.30%
Group 4 (80 to 99):  80.05%
Overall:             17.92%
Better than naive? Yes. Group 0 went from 0.05% to 4.75%. But honestly not by much. Overall accuracy only went from 16.93% to 17.92%.
Why does EWC struggle here? A few reasons:
The Fisher is a diagonal approximation. It assumes all parameters are independent which they definitely are not. Every interaction between parameters is ignored.
It accumulates across tasks. By Task 4 you're carrying Fisher estimates from 4 previous tasks, all computed at different points in weight space, and satisfying all of them simultaneously becomes increasingly impossible. The penalties start conflicting.
EWC works better in lower-dimensional parameter spaces or when tasks are more similar. With a ViT fine-tuned on 5 very different groups of classes, it just doesn't have enough precision to protect what matters.
Method 3: Experience Replay
Forget the math. What if you just kept some old examples around and showed them to the model during new task training?
That's Experience Replay. Maintain a fixed-size buffer of past examples. When training on Task 1, mix in some buffered examples from Task 0 alongside the new data. The model keeps seeing old stuff so it can't completely forget it.
The total loss becomes:
total loss = new task loss + replay loss
Where replay loss is just cross entropy on a random sample from the buffer.
The critical part is how you manage the buffer. With a capacity of 1000 samples across potentially 100 classes, you need to be smart about what stays in the buffer. I used reservoir sampling which guarantees that every sample ever seen has an equal probability of being in the buffer regardless of when it was seen. No recency bias, no task bias.
Reservoir sampling works like this: the first 1000 samples go straight into the buffer. For every new sample after that, generate a random integer between 0 and the total samples seen so far. If it's less than the buffer capacity, replace that slot in the buffer with the new sample. Otherwise discard. The math works out so every sample has equal representation probability.
Results:
Group 0 (0 to 19):   26.15%
Group 1 (20 to 39):  28.80%
Group 2 (40 to 59):  23.90%
Group 3 (60 to 79):  33.10%
Group 4 (80 to 99):  83.30%
Overall:             39.05%
This is a massive jump. Group 0 went from 0.05% (naive) and 4.75% (EWC) to 26.15%. Overall accuracy nearly doubled from EWC to 39.05%.
And notice the overall accuracy progression as tasks were learned:
After Task 0: 16.29%
After Task 1: 25.95%
After Task 2: 32.97%
After Task 3: 40.81%
After Task 4: 39.05%
The model is actually accumulating knowledge over time instead of replacing it. That's exactly what continual learning is supposed to do.
The small drop from Task 3 to Task 4 is the buffer getting stretched thin. 1000 samples across 5 tasks is only 200 per task on average, and within each task that's 10 samples per class. Extremely sparse. The model sees a tiny sliver of each old class and has to generalize from that.
But even so, ER with a 1000-sample buffer on 50,000 training images (2% buffer utilization) beats EWC by a massive margin. The actual data beats the mathematical approximation.
Method 4: EWC + ER Combined
EWC protects weights. ER provides old data signals. Can they work together?
In principle they attack forgetting at two different levels. ER keeps feeding the model old examples so the gradient signal from old tasks stays alive. EWC prevents the weights that process those signals from getting overwritten between replay steps.
The combined loss:
total loss = new task loss + replay loss + (lambda / 2) * EWC penalty
There is a potential conflict though. EWC penalizes weight movement including movement caused by replay gradients. If ER wants to move a weight to better classify an old example, EWC might penalize that exact move. So lambda matters more here than in standalone EWC. Too stiff and EWC actively suppresses the replay gradients that ER is trying to use.
Results:
Group 0 (0 to 19):   45.65%
Group 1 (20 to 39):  43.35%
Group 2 (40 to 59):  31.05%
Group 3 (60 to 79):  30.35%
Group 4 (80 to 99):  77.00%
Overall:             45.48%
Best overall accuracy. Best old task retention. Group 0 at 45.65% after 4 subsequent tasks is genuinely impressive given that Task 0's data has been gone since the beginning.
The trade-off: current task accuracy dropped slightly. Group 4 went from 83.30% (ER alone) to 77.00% (EWC+ER). The EWC penalty is constraining plasticity a little. You're paying about 6% on the current task to retain significantly more of the old ones. Whether that trade-off is worth it depends on your use case.
The Upper Bound: Joint Training
To put everything in context I also trained on all 100 classes simultaneously. No sequential constraint. Just feed it everything and let it learn.
Overall accuracy: 68.07%
Per group: all groups in the 64 to 71% range
This is the ceiling. The best continual method (EWC+ER at 45.48%) is 22.59 percentage points below joint training. That gap is the fundamental cost of the sequential constraint. You're paying 22.59% in accuracy just because your data arrives in chunks instead of all at once.
Here's the full picture:
Joint Training:   68.07%   (upper bound, not a CL method)
EWC + ER:         45.48%   (67% of joint performance)
ER:               39.05%   (57% of joint performance)
EWC:              17.92%   (26% of joint performance)
Naive:            16.93%   (25% of joint performance)
Untrained:         1.04%   (random baseline)
One more interesting thing. On the most recent task (Group 4), naive and ER actually beat joint training:
Naive Group 4:       83.95%
ER Group 4:          83.30%
Joint Training G4:   70.90%
Why? Because naive and ER spent 3 epochs fine-tuning specifically on Group 4's 10,000 images with laser focus. Joint training had to balance gradients from all 100 classes simultaneously, so no single group gets that concentrated attention. The sequential methods are overtrained on the current task. That's exactly the problem we're trying to solve.
What I Learned
Replay beats regularization here by a lot. EWC going from 16.93% to 17.92% while ER jumps to 39.05% tells you that the actual data beats the mathematical approximation of what the data implied. If you have any ability to store old examples, do that before reaching for regularization.
The combination is genuinely synergistic. EWC+ER at 45.48% beats both ER (39.05%) and EWC (17.92%) individually. They're not fighting each other at lambda=400, they're cooperating. The weight anchoring from EWC gives the replay gradients a more stable foundation to work on.
Buffer management is everything in ER. If you use a FIFO queue instead of reservoir sampling, old task samples get evicted as new task data floods in and you lose the benefit completely. Reservoir sampling is not optional.
Class-IL is genuinely hard. These numbers would look much better in a task-incremental setting where the model gets told which task it's being evaluated on. In class-IL it has to figure out everything from 100-way softmax with no hints. The 22.59% gap to joint training is the real cost of that difficulty.
Single seed results are unreliable. I ran this once per method. On a second run the numbers shifted by 2 to 3 percentage points on some groups. The rankings stayed the same but the specific numbers moved. If you're doing something similar, run at least 3 seeds and report mean ± std. For a blog post like this, take the exact numbers with some salt.
What's Next
This experiment used some of the simpler continual learning methods. There's a whole family of more sophisticated approaches worth exploring:
Parameter isolation methods like PackNet which actually carve out separate subnetworks per task and prevent any interference by construction. No forgetting by design but you run out of capacity fast.
Generative replay where instead of storing old examples you train a generative model to synthesize them. Privacy preserving because you never store real data but the generated examples need to actually look like the real distribution.
Gradient Episodic Memory (GEM) and its variants which project gradients to prevent interference with past tasks directly in gradient space rather than weight space.
Dark Experience Replay which stores not just labels but the model's own soft predictions on old examples and replays those. More information per stored sample.
The field is moving fast and the gap to joint training is still large. 22.59% is a lot of accuracy to leave on the table. Someone's going to close it.
Code for this experiment is on my GitHub if you want to run it yourself. The full notebook has all four methods, the eval functions, and the forgetting curve plots.